More AI Usage.Less AI Cost.Secure Inference
Give developers more AI capacity for coding, reasoning, and long-running agentic workflows without building or operating your own GPU infrastructure.
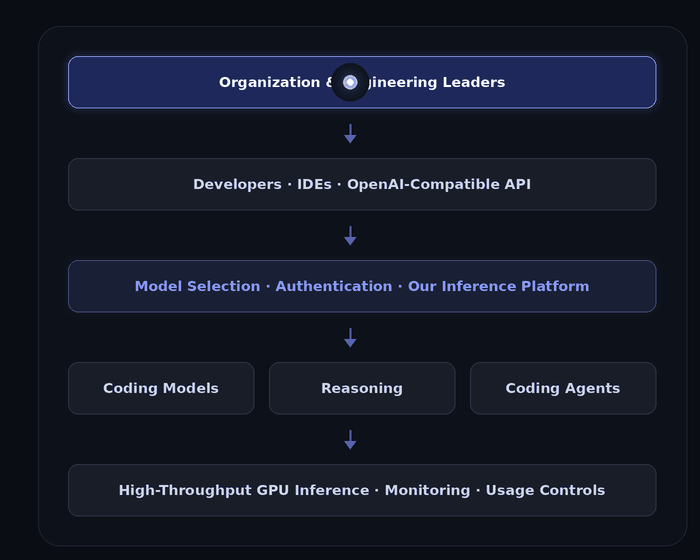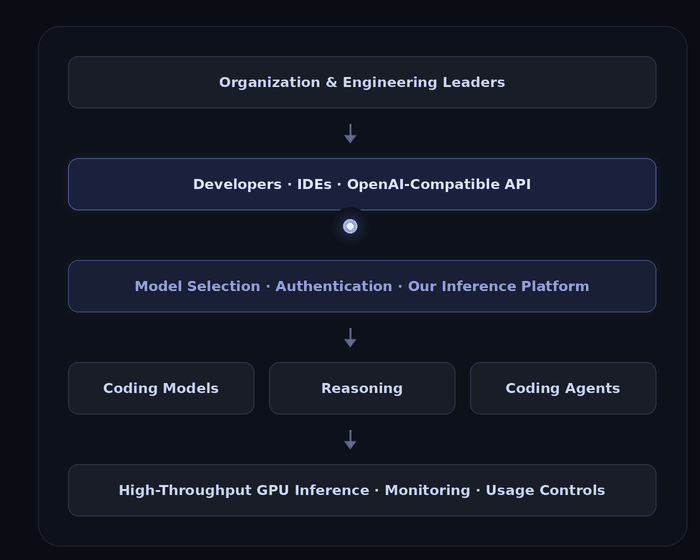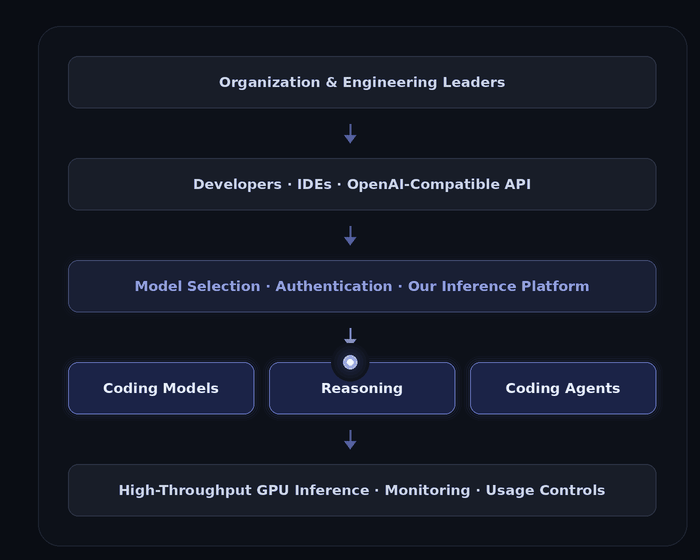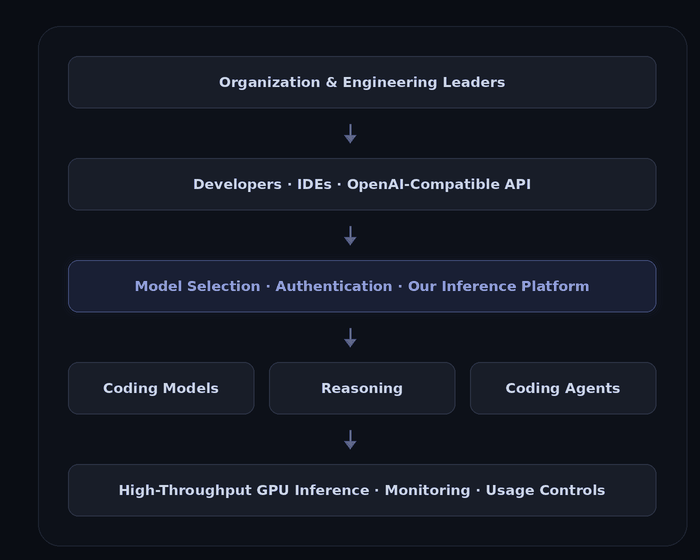
Who It's For
Built for Organizations Scaling AI-Assisted Development
Mangix AI is purchased and enabled by organizations, then used every day by their developers. Give engineering teams more capable coding assistance and longer sessions while keeping budget, access, visibility and security under organizational control.
Software Companies
Connect coding tools, agents and applications to OpenAI-compatible inference built around software workflows.
Engineering Organizations
Give development teams more capacity for implementation, debugging, refactoring and long-context work.
Security-Conscious Organizations
Keep source code, data and prompts on a controlled inference path while giving teams access to modern coding models.
Growing Development Teams
Scale coding inference capacity predictably as more developers adopt AI for complex daily tasks.
IT & Platform Teams
Provide a managed, observable inference service that can be rolled out across development teams with clear usage controls.
Technology Leaders
Enable developers with high-end coding assistance without the cost and operational burden of running a dedicated GPU stack.
The Problem
AI Adoption Is Growing. So Are the Costs and Risks.
Rising AI spend, sensitive data exposure, unclear retention, vendor dependency, limited infrastructure control, and unpredictable usage can make scaling AI harder than it should be.
Rising AI Costs
Per-seat subscriptions and API usage can become expensive as teams scale and adoption grows.
Sensitive Code & Business Data Exposure
Source code, prompts, documents and business information sent to public AI providers can leave your controlled environment.
Unclear Data Retention
Provider terms and retention settings can be difficult to understand, audit or align with your internal security policy.
Limited Control
Companies may have limited control over infrastructure, model deployment and where data processing occurs.
Usage and Capacity Constraints
Token-based billing can grow faster than expected as AI usage spreads across the organization.
Vendor Dependency
Organizations can become heavily dependent on a small number of AI providers and their pricing decisions.
The Solution
More Coding Inference Capacity Without Running Your Own GPUs
We give developers a focused endpoint for high-potential open-source coding models without asking your organization to buy, configure or maintain its own GPU stack. We operate the inference capacity while your teams retain the controls, visibility and access policies needed for responsible adoption, so your team can focus on building the softwares and AI products for your organization.
- Longer coding sessions
- Code protection
- Predictable billing
- Secure access
- More inference capacity
- Open-source model access
- Coding model selection
- IDE integration
- Organization controls
- Usage tracking
- Monitoring
- Team administration
Developer Integrations
Easy Integration With the Tools Your Developers Already Use
Connect a coding-focused endpoint to the IDEs, CLIs, agents and applications you already use. OpenAI-compatible APIs make it easier to bring more inference capacity into your development workflows.
Use Cases
What Developers Do With More Inference Capacity
Repository-Scale Reasoning
Work across larger codebases with models selected for context handling, reasoning and software engineering.
Long Coding Sessions
Keep your coding assistant available for the sustained context, iteration and reasoning that serious development requires.
Coding Inference API
Connect your IDE, CLI, extension or development tool to a reliable coding-focused inference endpoint.
Coding Agents
Give agent workflows the context window and inference capacity needed for multi-step software tasks.
Code Generation & Refactoring
Use capable open-source coding models for implementation, explanation, migration and test generation.
Debugging & Root Cause Analysis
Get more context and reasoning for code explanation, bug detection, & root cause analysis.
Coding Inference Plan Calculator
Find the Capacity for Your Coding Workload
Enter your developer count and current AI spending, choose the coding inference capacity you need, and compare the monthly plan cost. Calculations use the USD prices published on our Pricing page.
What is your current public-AI bill?
Current public-AI bill: $59,980/month
Give Your Engineering Team the Best Inference Capacity they need.
Enable developers with high-potential open-source coding models, longer demanding sessions and an organizationally controlled coding inference service.
To activate your plan or free trial, call or email us directly at hello@privateai-infrastructure.comor+91 00000 00000
Tell us about your organization and coding workload
Share your team size, tools, coding tasks and capacity needs. We will recommend a suitable organizational inference plan.
FAQ
Common Questions
What is inference capacity?
The ability to run models with more context, reasoning and multi-step capabilities than typical AI subscriptions.
What is Coding Inference as a Service?
A managed endpoint that gives developers access to selected open-source coding models without requiring them to operate their own GPU infrastructure. Its plug-and-play API is compatible with OpenAI endpoints and IDE integrations ready.
Which models do you provide?
We focus on open-source models with strong coding, reasoning, long-context and agent capabilities. Available models can change as quality and licensing evolve.
Why use Mangix AI instead of a public AI subscription?
The service is designed around coding capacity: more room for sustained development, repository-scale reasoning, code generation and coding agentswhile maintaining data privacy and compliance.
Can developers use it from VS Code or Similar IDEs?
Yes, through OpenAI-compatible APIs and supported editor integrations configured for the service.
Can I use it for coding agents?
Yes. Solution is designed for agent workflows and multi-step tasks, It also supprts tools and vision capabilities for high-level coding tasks.
Is my source code stored?
No. we operate under zero data retention policies. The service does not store or retain source code, prompts or data. All inference is performed in memory and results are returned to the calling application.
Can we use open-source models commercially?
Many models permit commercial use, but terms vary by model and version. Model licensing should be reviewed before production use.
How much more coding capacity do I get?
Capacity depends on the plan, model, context length, concurrency and workload. The calculator provides an indicative plan comparison.
How does billing work?
Plans are priced per developer or by agreed team capacity. Enterprise or high-throughput requirements can be configured separately.
Do I need to buy a GPU?
No. The managed service is designed to provide inference capacity without requiring you to purchase and operate your own GPU stack.
Can we start with a small developer group?
Yes. A small group is a practical way to evaluate model quality, latency, workflow fit and capacity before scaling.